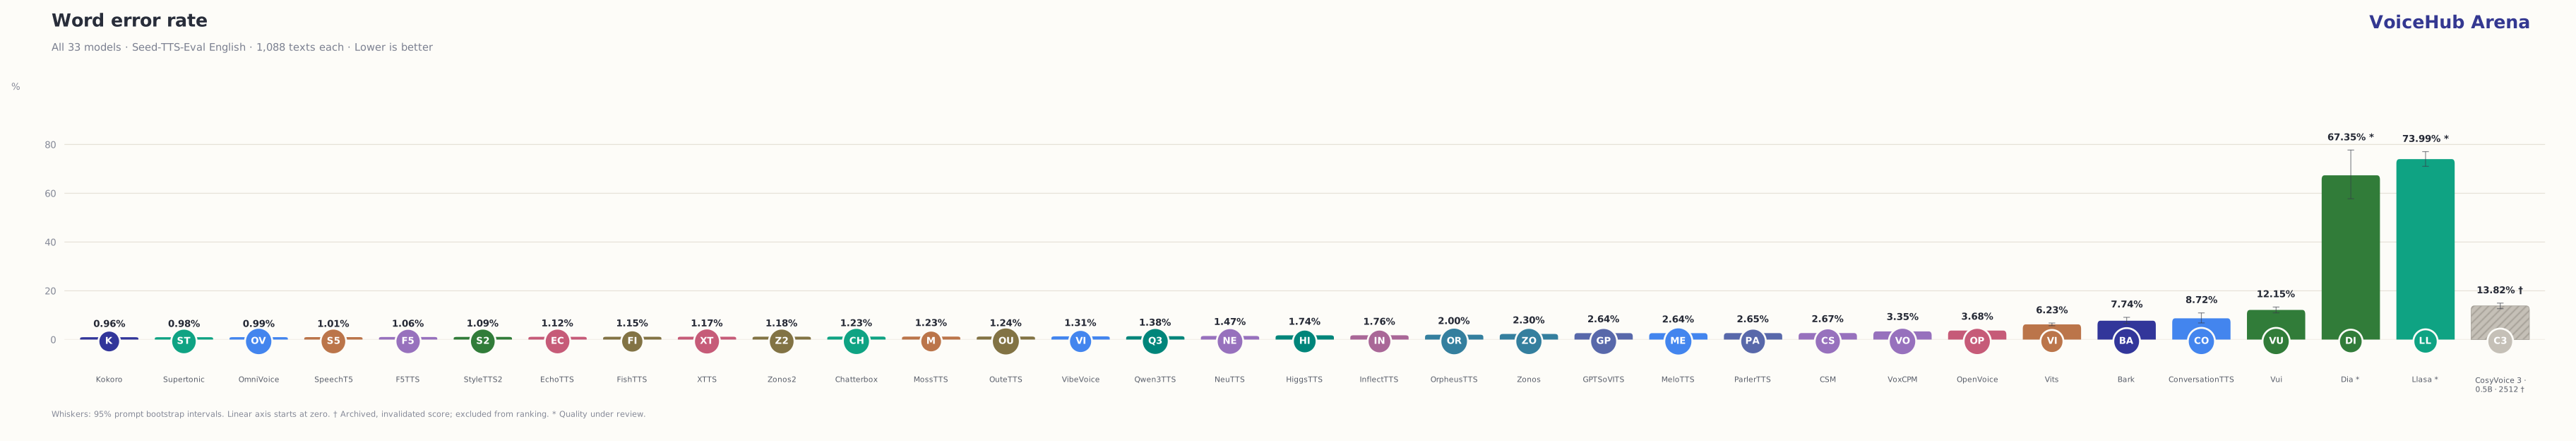
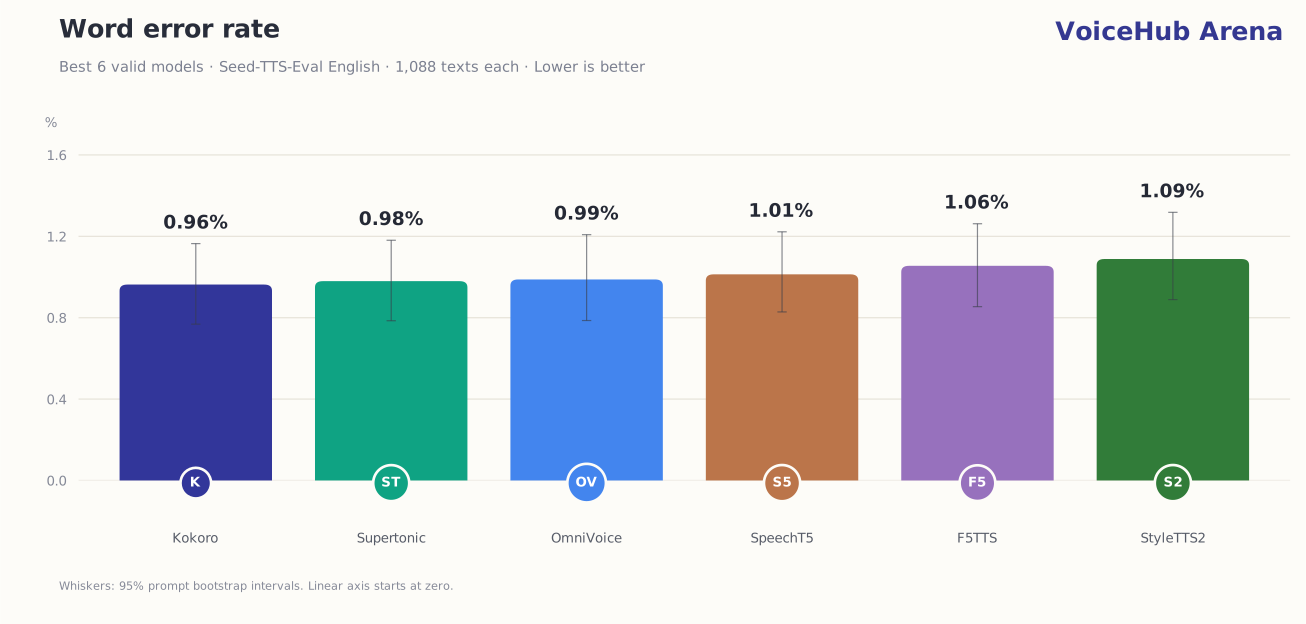
Word error rate
Lower is better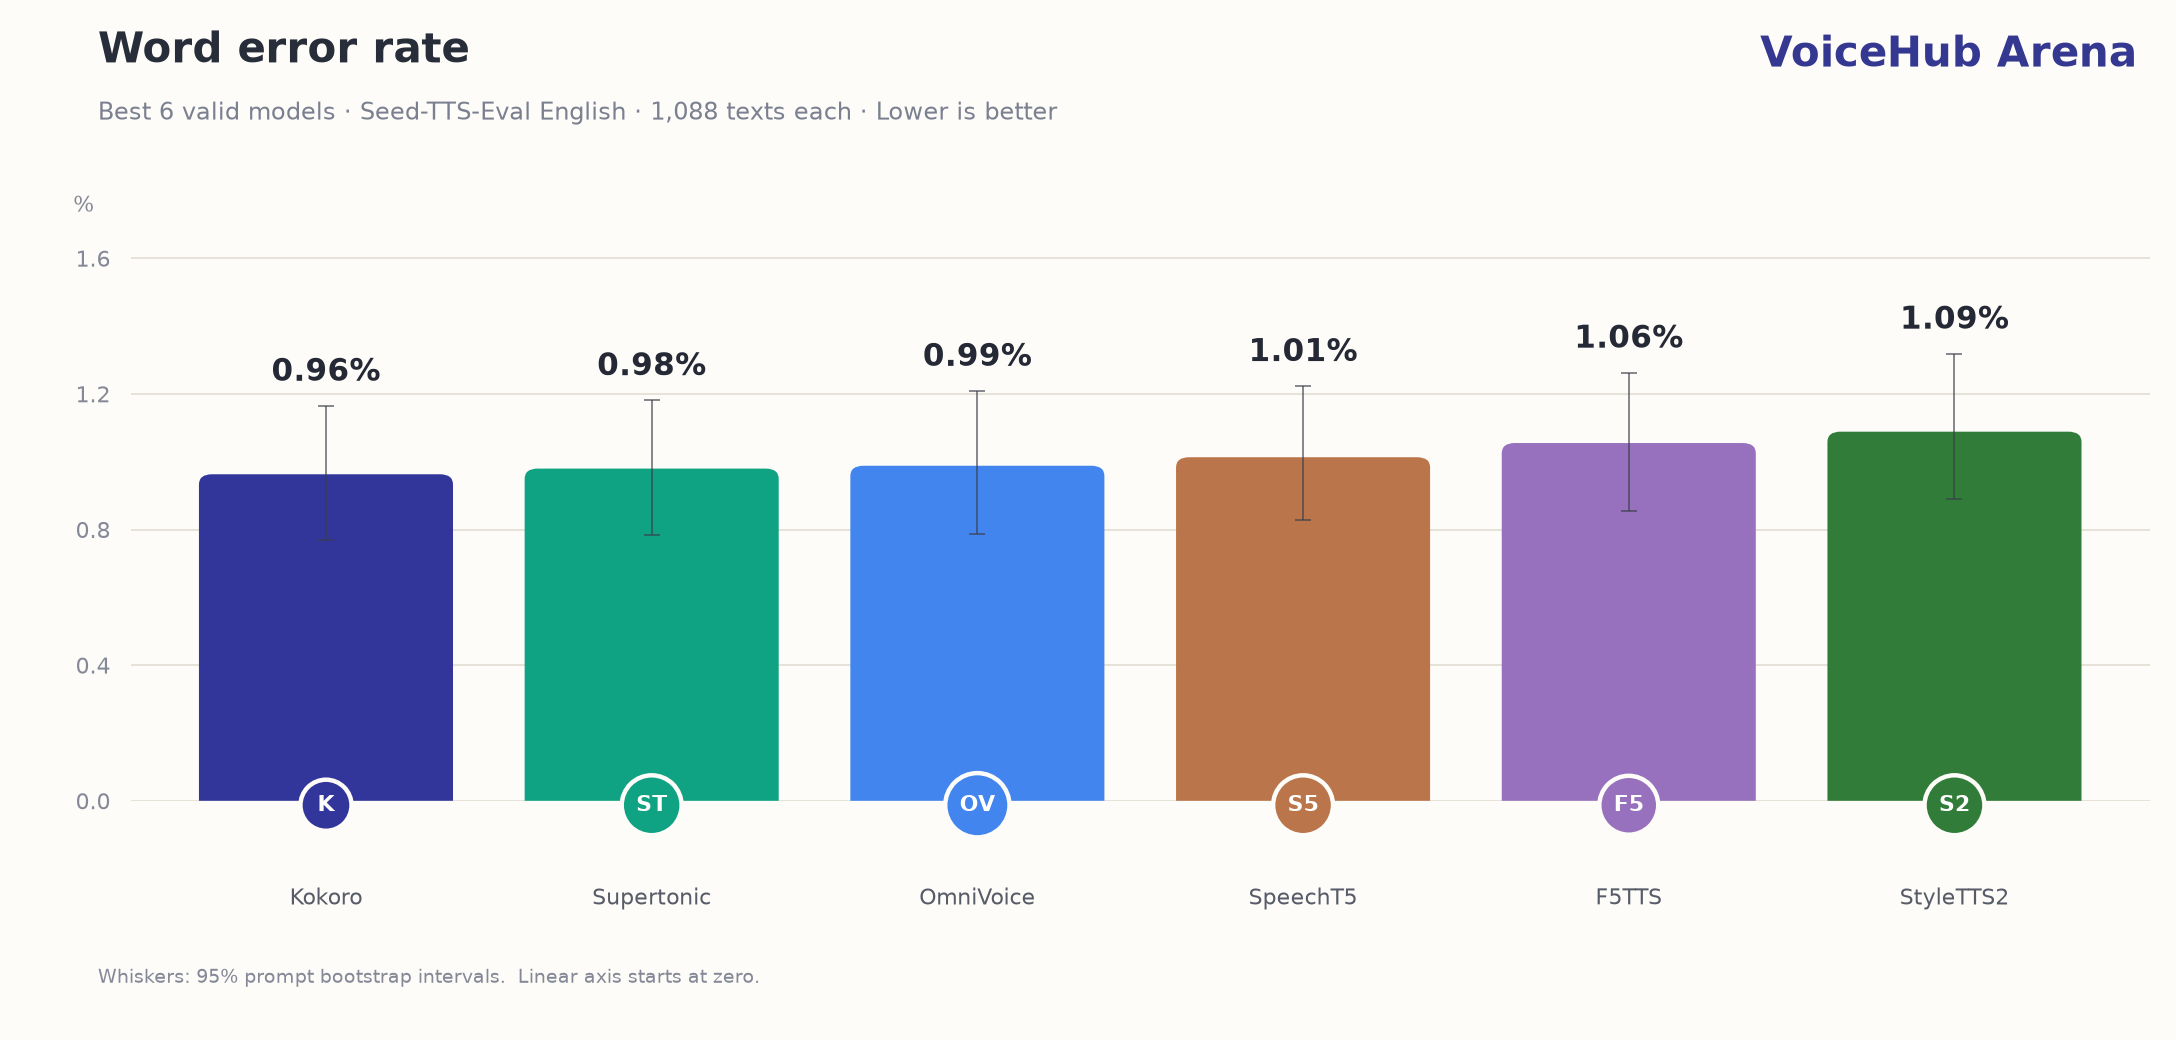
Compare 33 text-to-speech models on the complete English Seed-TTS-Eval split. Every score has a transcript. Every transcript has a recording.
Whisper-large-v3 transcription
Fixed provider voices & references
Same 1,088 texts for every model
Choose a metric. Compare the bars. Inspect the full table below.
Same texts. Same evaluator.
1,088 samples for every model.
| Model | WER | 95% confidence interval |
|---|
Corpus error rates. Lower WER, CER and RTF are better.
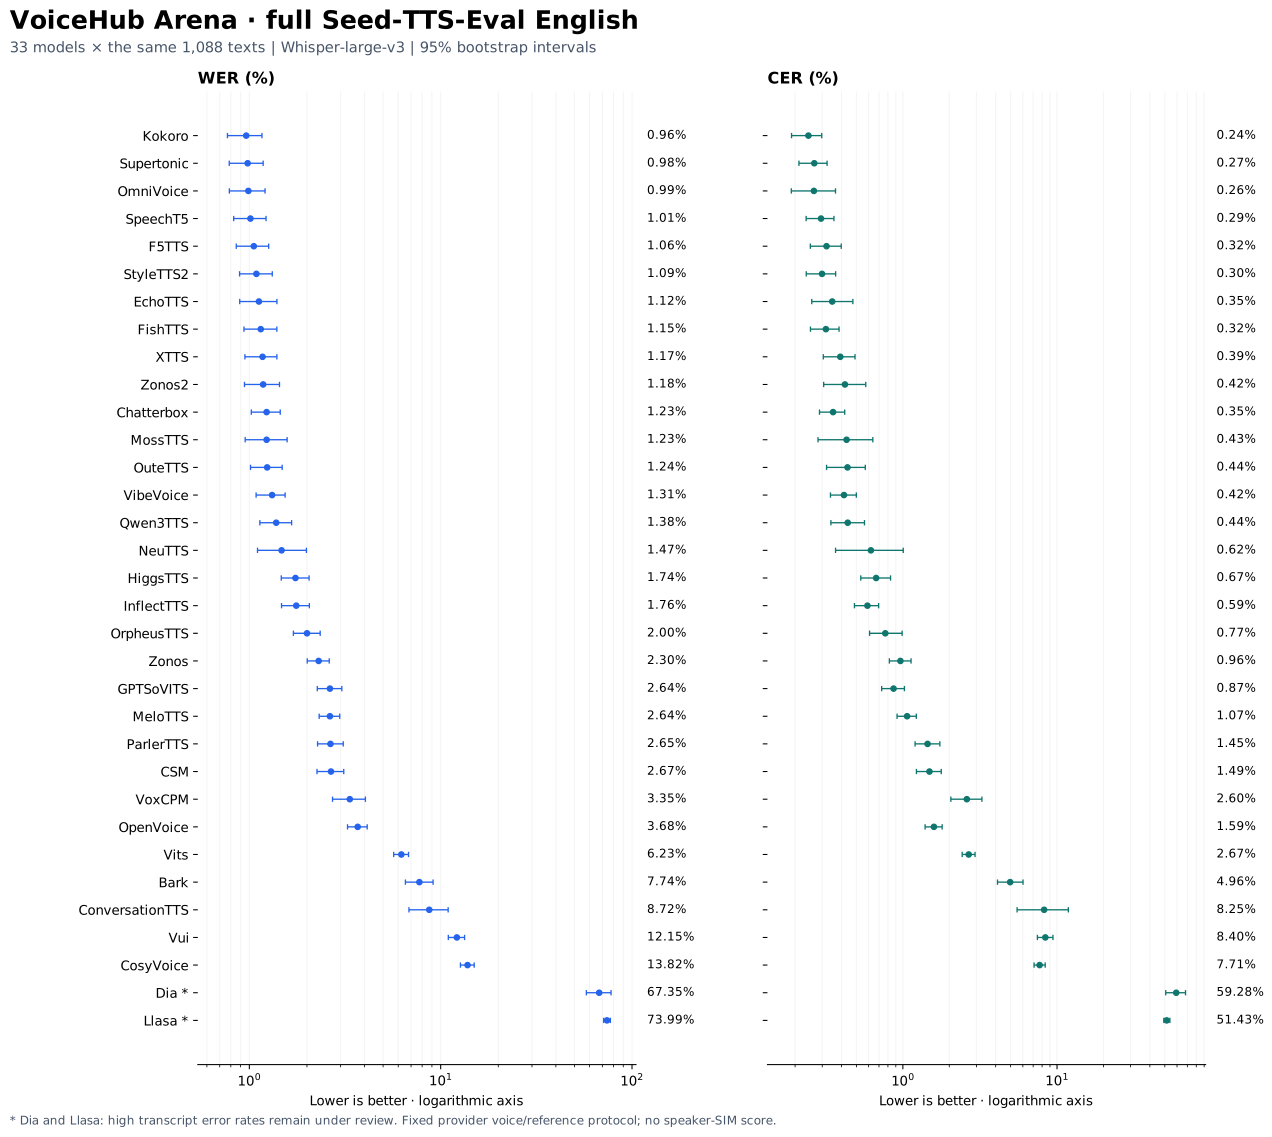
Select a model name to listen to its samples. WER/CER intervals are 95% prompt bootstrap intervals; small rank differences may not be meaningful. ● Review marks a confirmed or unresolved quality issue. CosyVoice’s archived score has no rank.
All 1,088 texts per model, with targets, ASR transcripts and original WAV files.
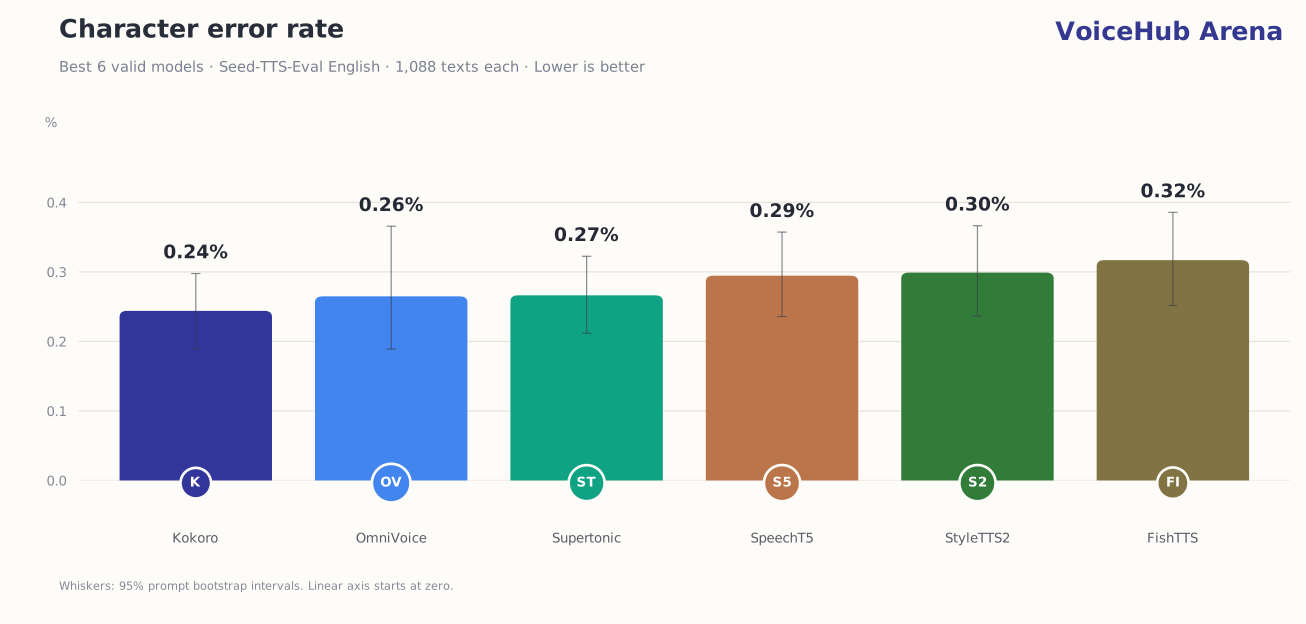
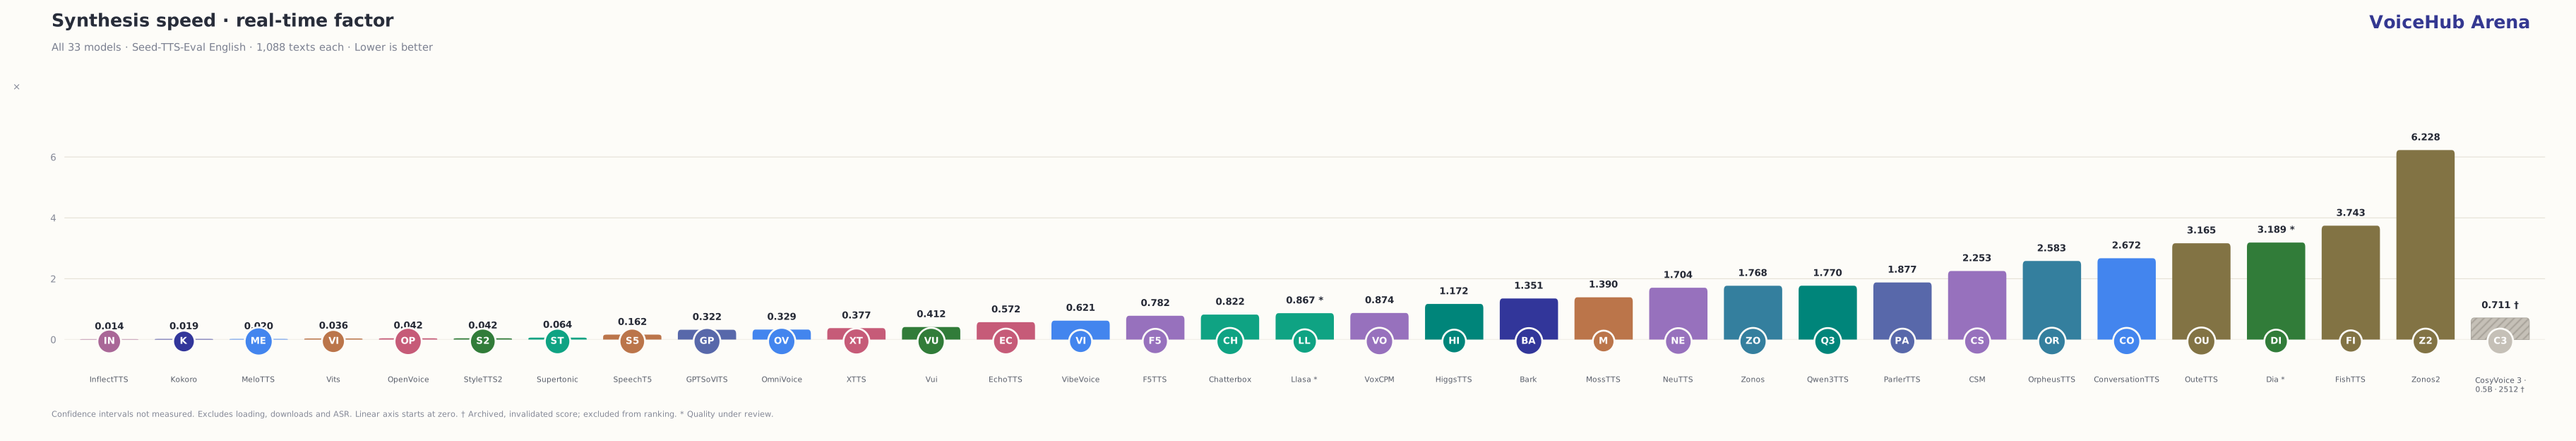
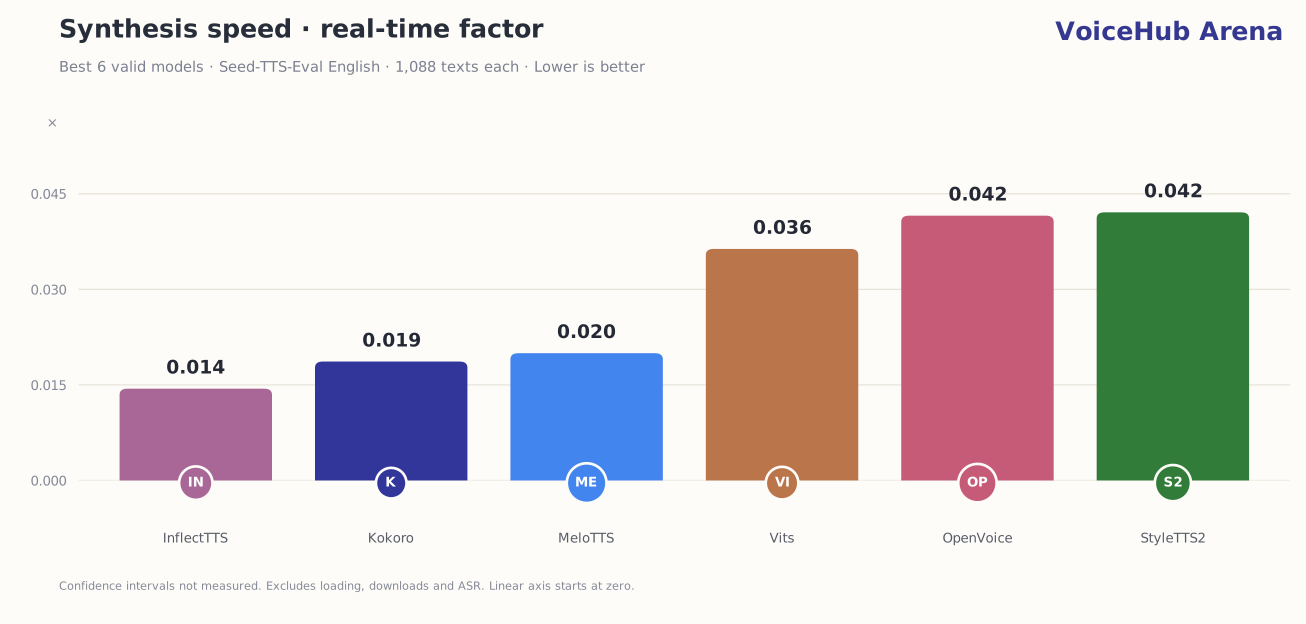
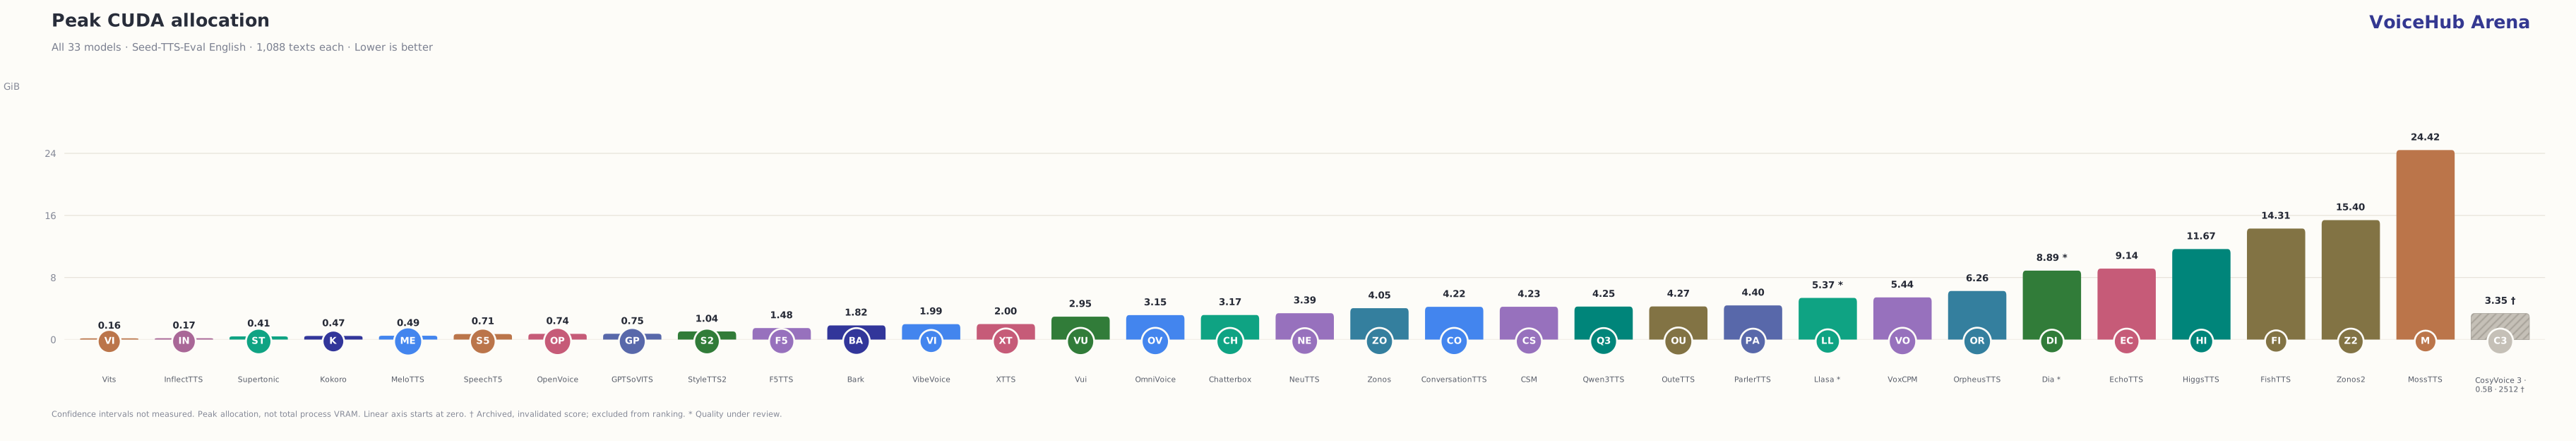
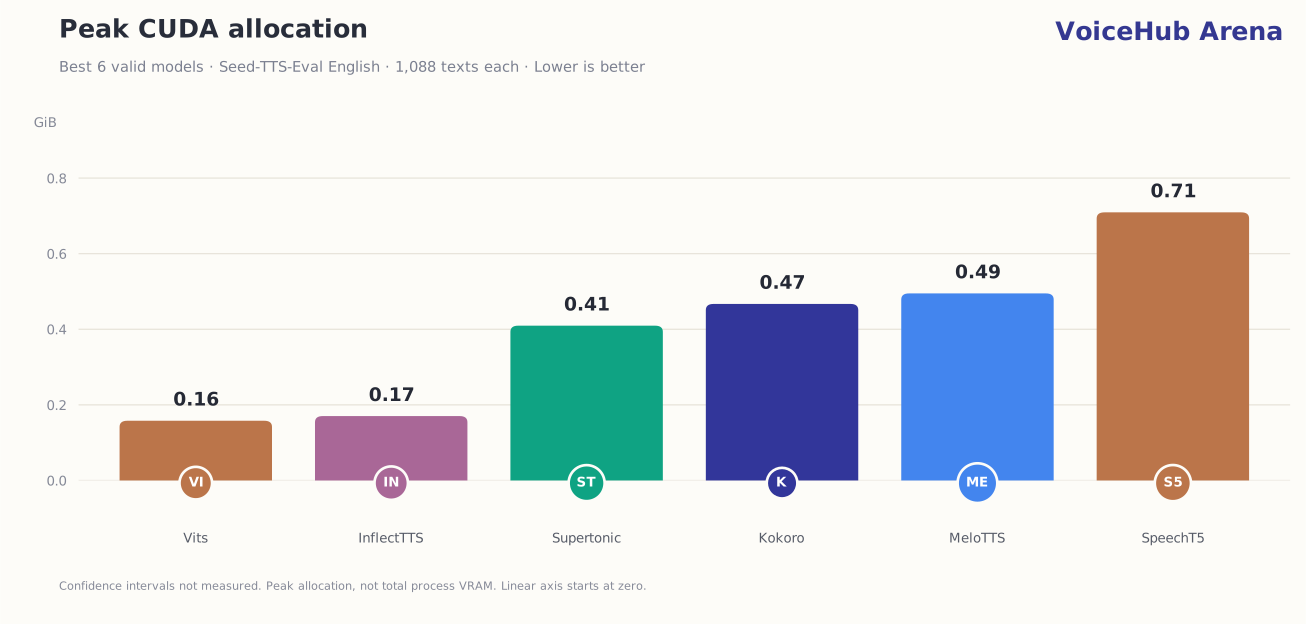
Preview the best six for each metric. Download the full 33-model chart as PNG or SVG.
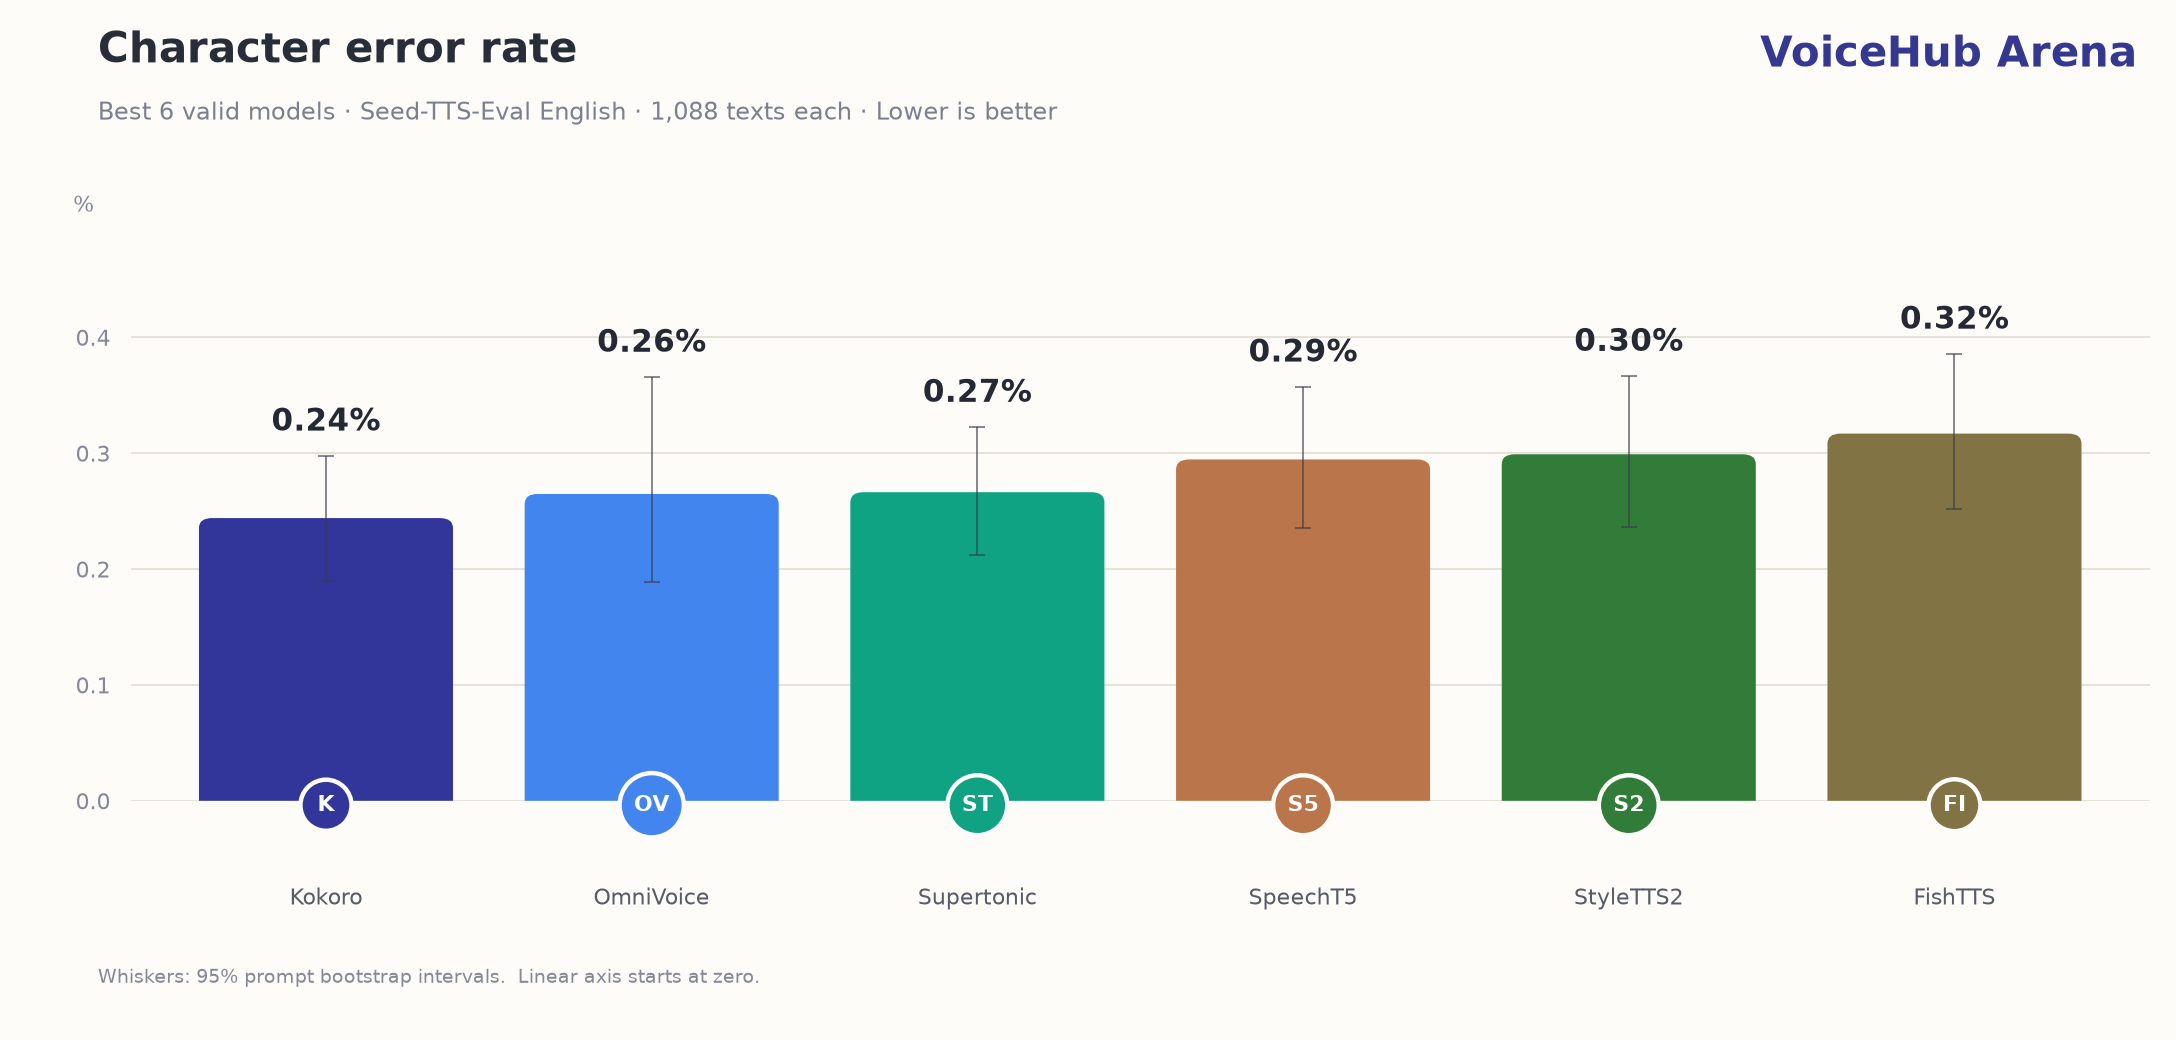
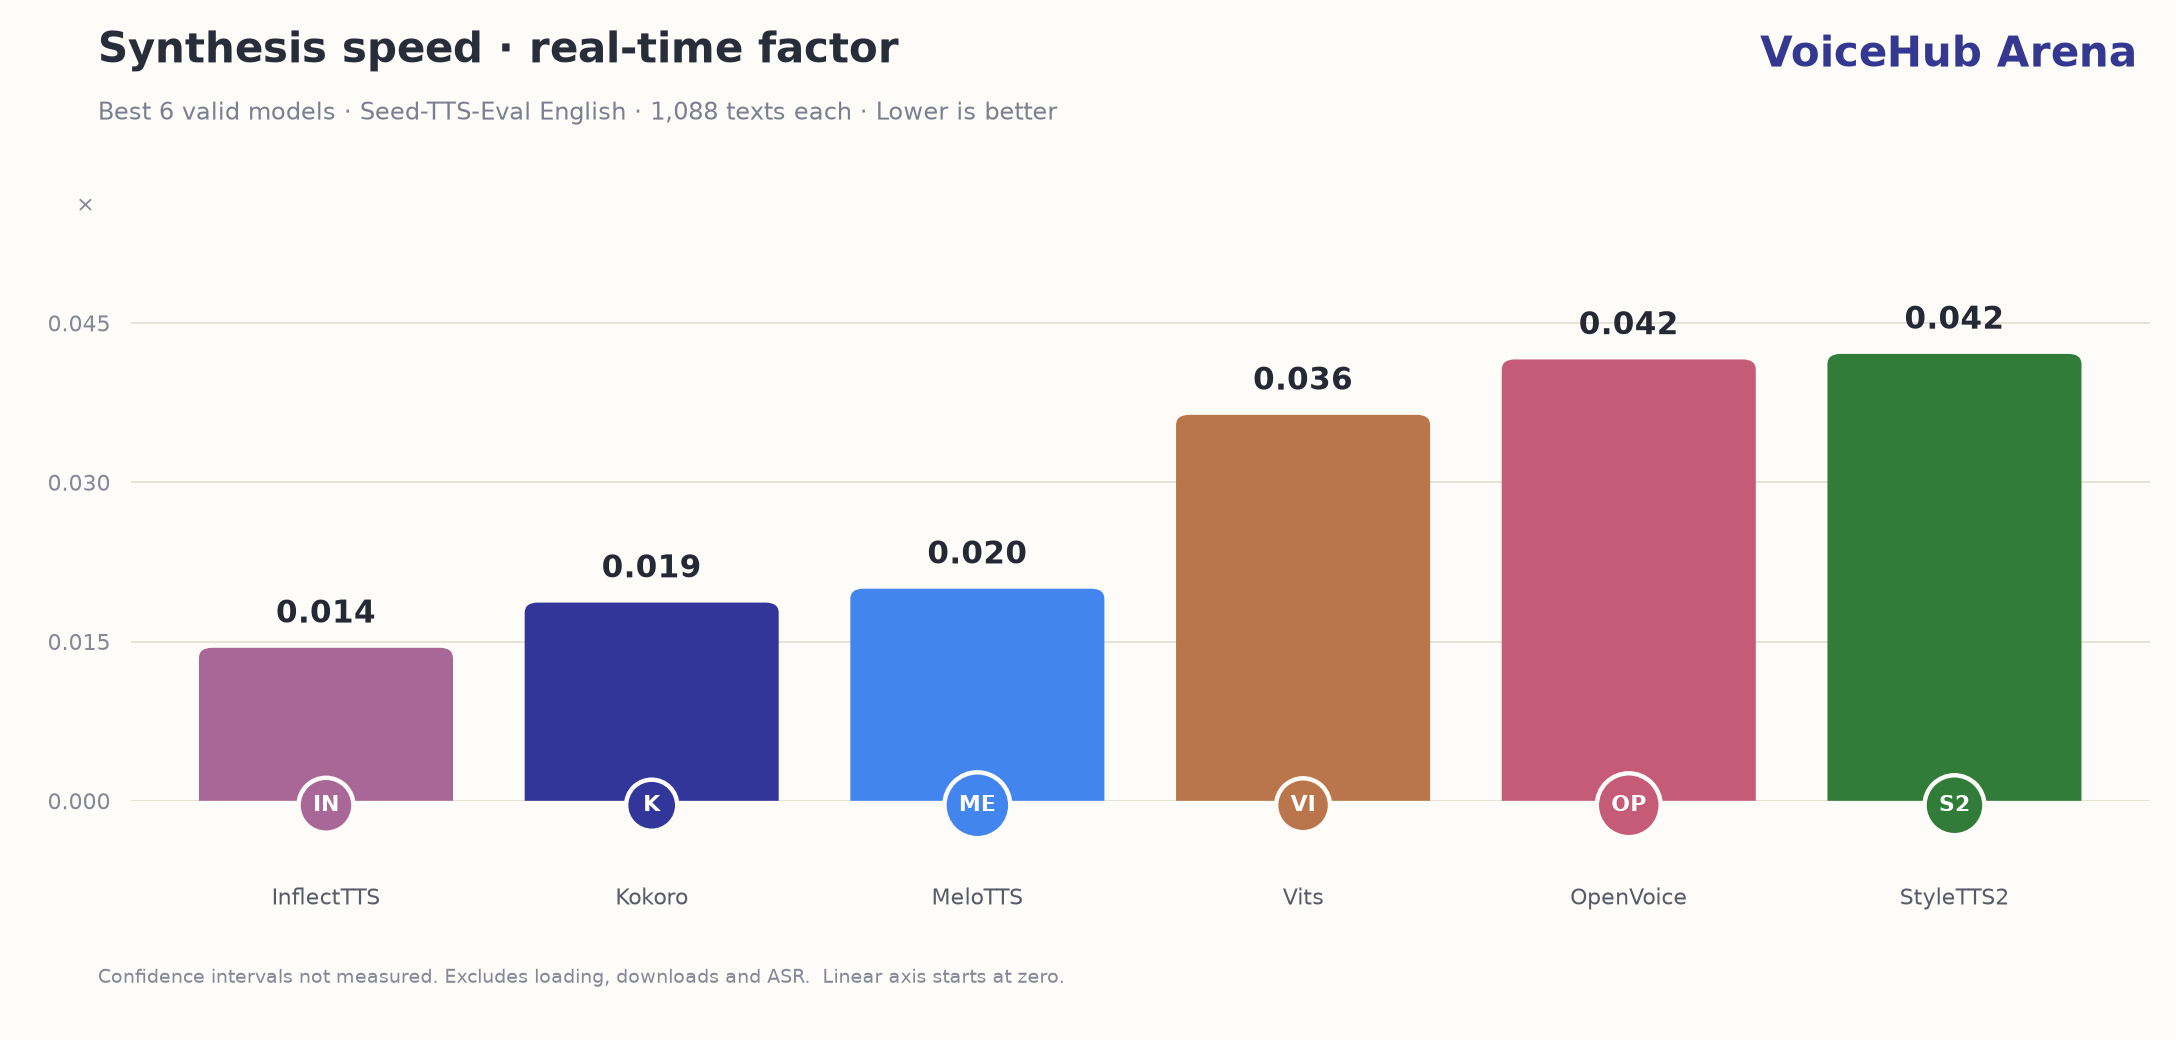
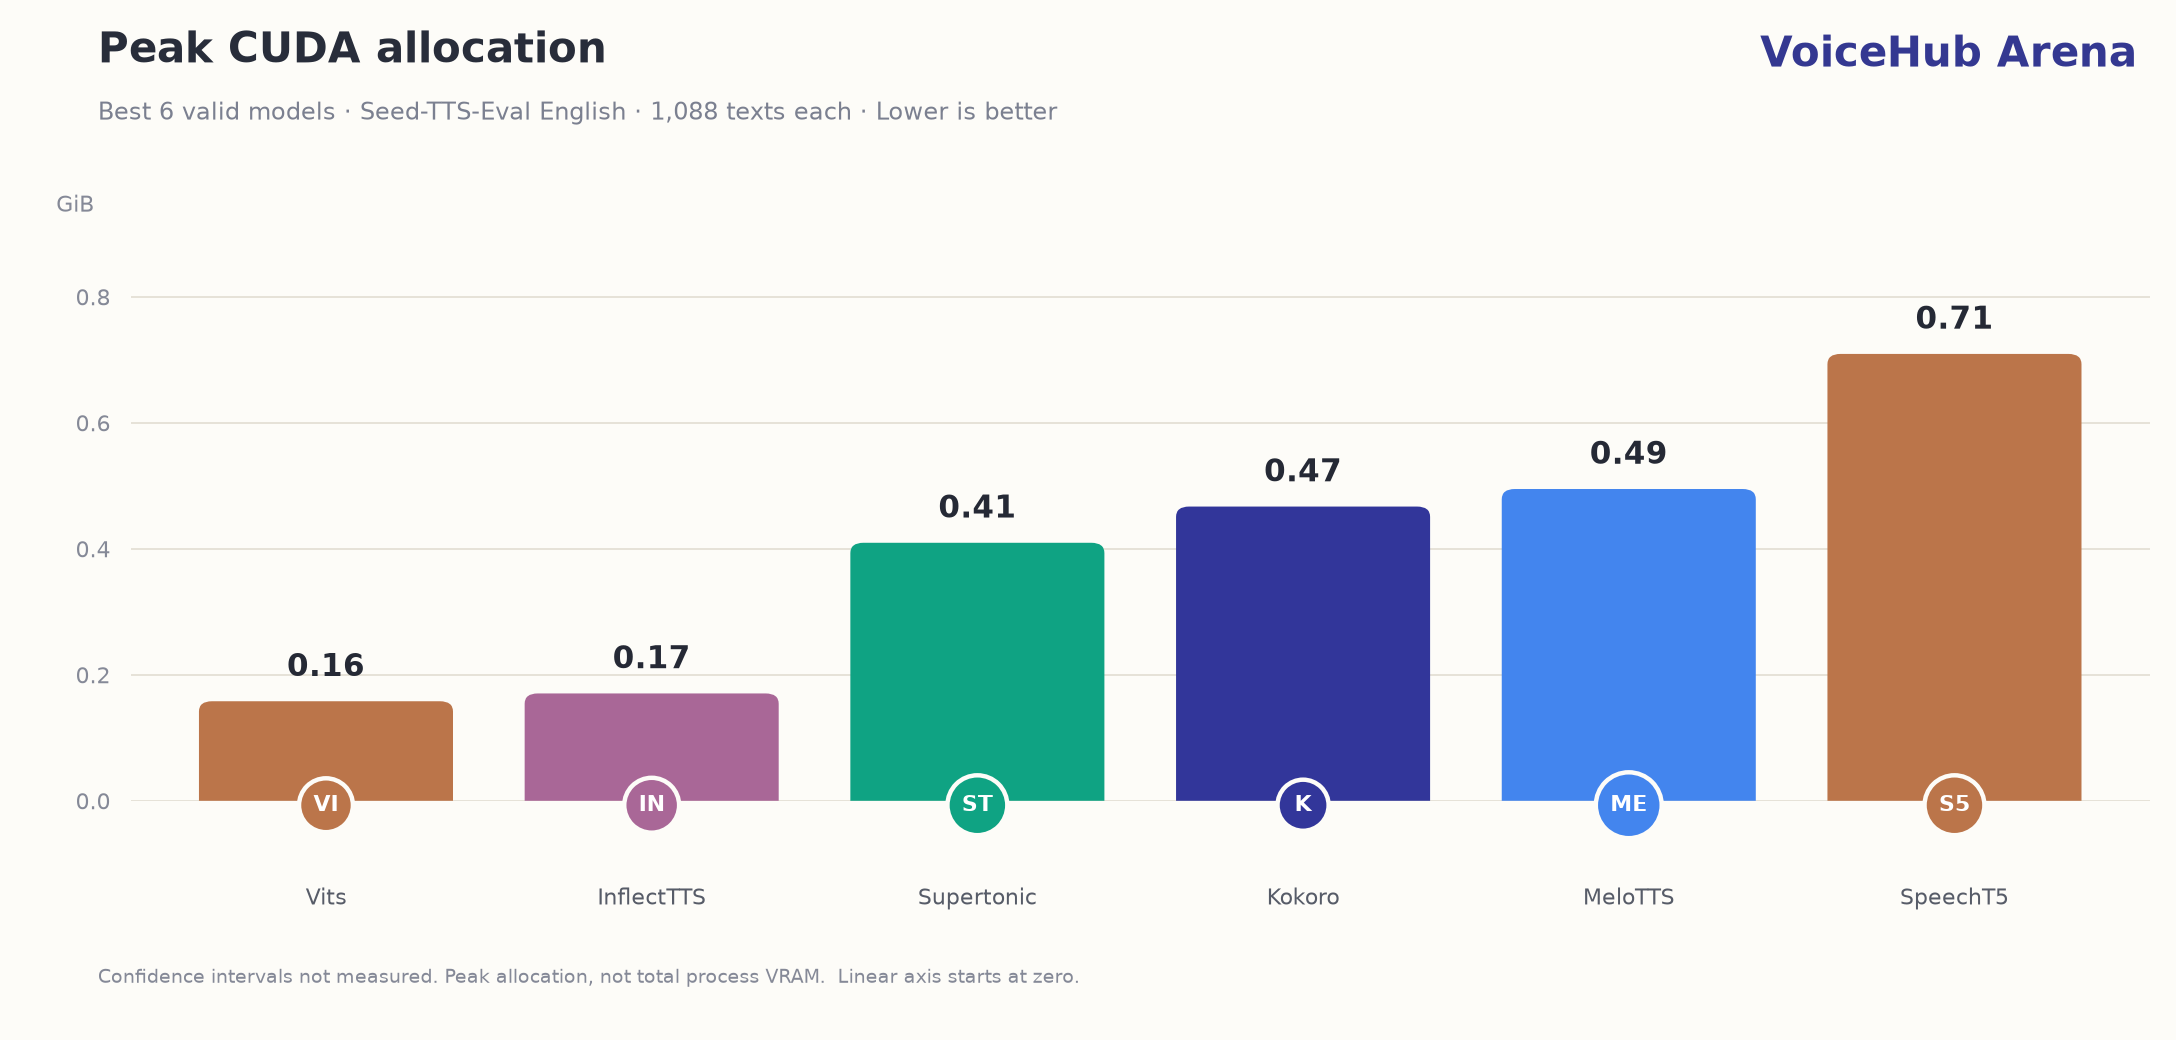
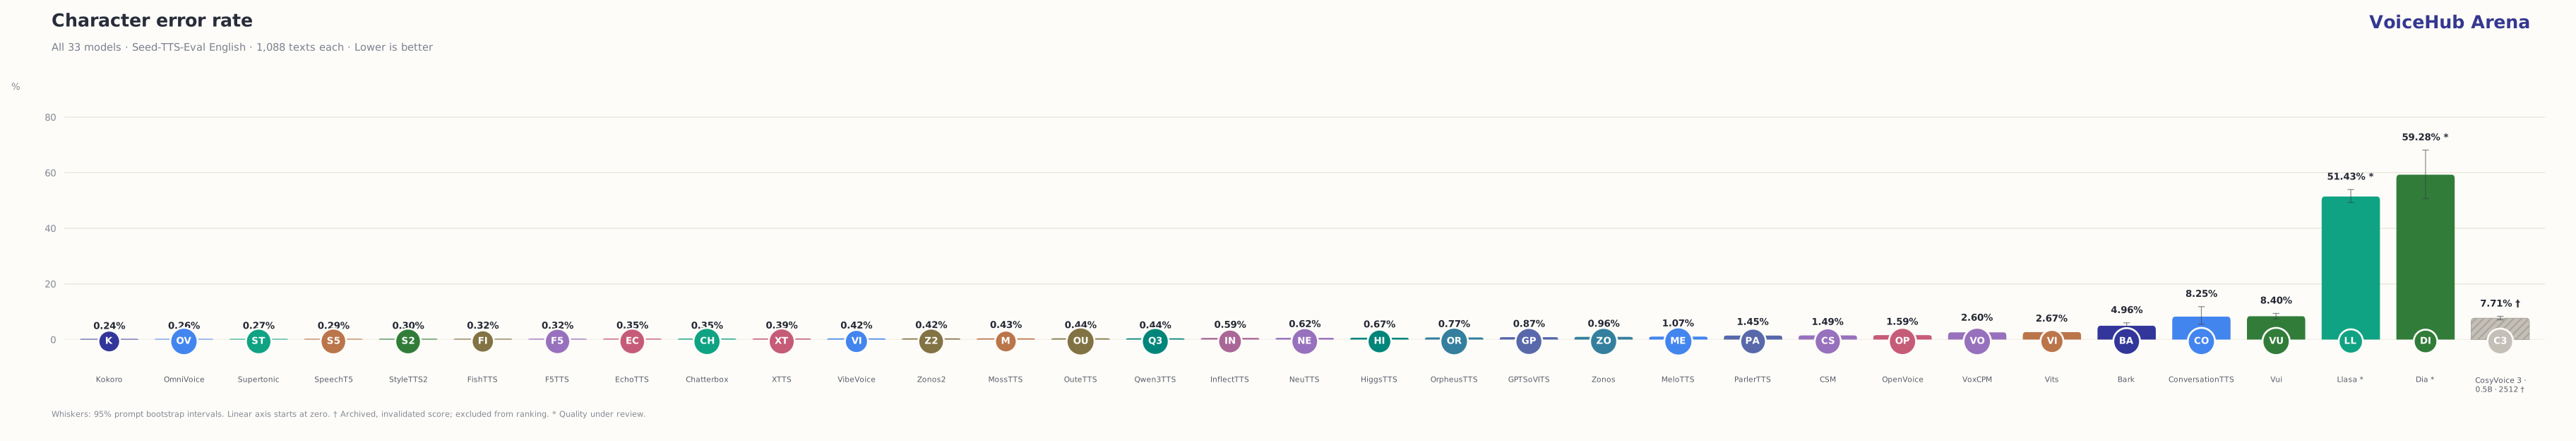
Every axis starts at zero. WER/CER whiskers are 95% prompt bootstrap intervals. Speed and memory have no measured confidence intervals. Best-six views exclude invalidated scores; full charts retain them with a hatched bar and † marker. * indicates quality under review. These are measured benchmark values, not Elo ratings.
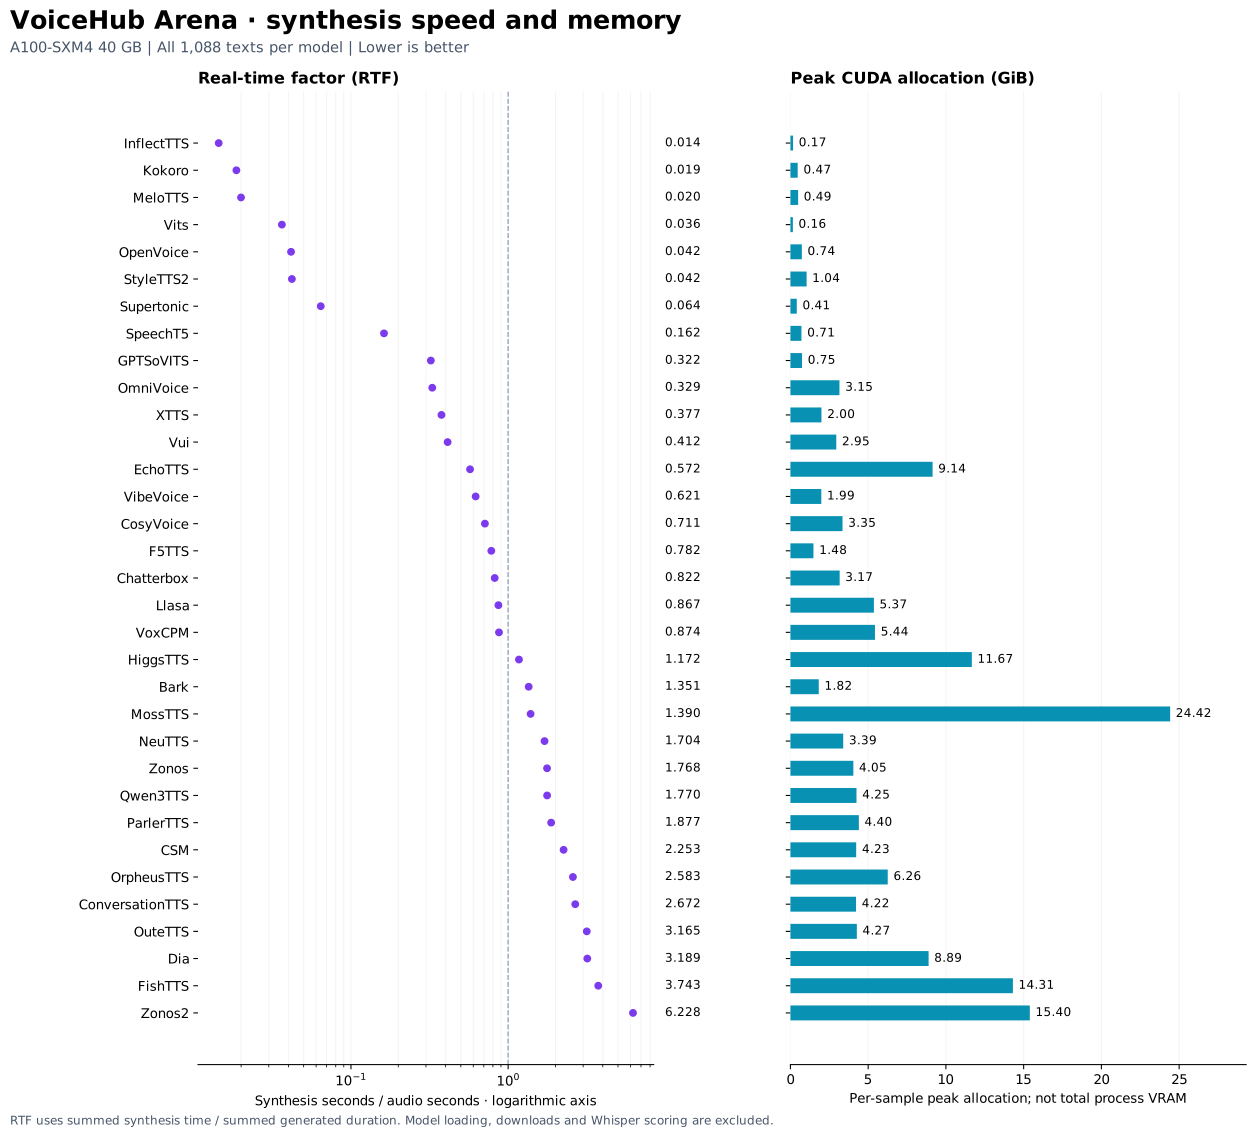
Original full-run plots. The CosyVoice score shown here was subsequently invalidated; see the quality audit. Current review markers are included in the new bar charts above.
Logarithmic axes, with 95% confidence intervals. All models remain visible.

RTF excludes loading, downloads and ASR. Memory is peak CUDA allocation, not total process VRAM.

All 33 models synthesize the same 1,088 English texts with seed 42 and one repeat. WER and CER aggregate edit counts across the corpus, rather than averaging shard percentages. Recognition uses pinned Whisper-large-v3 and whisper_english normalization.
WER measures word edits; CER measures character edits. Both estimate intelligibility through ASR. They do not measure naturalness or speaker similarity. Fixed provider voices and references mean this is not the official zero-shot speaker-identity/SIM protocol.
CosyVoice has a confirmed vocoder defect in this archived run. Dia and Llasa completed inference but have high transcript error rates whose causes are still under review. Their outputs are included. Empty ASR text alone does not prove silence. Successful inference is not a guarantee of good speech.
MER / WIL / WIP: match error rate, word information lost and word information preserved. Lower MER/WIL and higher WIP are better. Exact match: fraction of normalized target/transcript pairs that match exactly.
RTF: summed synthesis seconds / summed audio seconds; below 1 is faster than real time. Latency p50/p95: synthesis time percentiles. Silence/clipping: measured signal diagnostics, not subjective quality ratings.
ASR: Systran/faster-whisper-large-v3, revision edaa852ec7e145841d8ffdb056a99866b5f0a478; CUDA FP16, English, beam 5, temperature 0, no VAD or previous-text conditioning. 95% intervals: 1,000 prompt-cluster bootstrap resamples, seed 42.
Coverage verification · Audio hash verification · Original Seed-TTS-Eval